2. Data Analysis Methodologies and Procedures
2-6. Items Required for DATA Analysis and Analysis Logic
The true purpose of data analysis lies in accurately expressing current logistics facts with numerical data, objectively indicating how equipment, personnel, space, and operational hours will change by introducing a proposed system.
1) Constituents of Shipping Data (EIQ + Extended Items)
The foundation of distribution center design is EIQ Analysis (E: Entry/Destination, I: Item, Q: Quantity), but advanced warehouse design cannot be performed using mere information like "10 items of Product B were shipped to Destination A." Tera Calculation adopts a shipping data import format consisting of the following basic and additional items.
| Item Name | Description and Operational Role |
|---|---|
| Row Sequence Number | Sequential line number of shipping data records. |
| Shipping Date & Time | Actual shipping date and time slot. Used for hourly volume aggregation and shipping fluctuation analysis. |
| Destination (Entry) | Delivery location where products are delivered (company name, store name, delivery hub code). |
| Item (Item) | Product code or product name identifiable at the SKU (Stock Keeping Unit) level. |
| Piece Quantity (Quantity) | Minimum management unit in ordering, labor, and management (SKU quantity). |
| Case Pack Quantity | Master benchmark value to calculate converted case values from piece quantities and automatically classify case/piece shipping. |
| Pallet Case Stacking Quantity | Number of cases stackable per pallet (PL). Used to derive converted pallet values from case counts. |
| Case Volume & Weight | Outer dimensions volume (m³) and gross weight (kg) per case. Used to convert piece quantities into volume and weight. |
| Item Category & Shipping Category | Flag items to extract or exclude specific analytical scopes (e.g., excluding direct shipments). |
| Shipping Route | Route name managing load groups or delivery courses loaded onto the same truck. |
2) Data Scale Sense and Simple Aggregation
An example of data scale sense in a general analysis model (assuming BtoB centers for small electronics, etc.):
- Total Record Count: Approx. 60,000 rows (records)
- Scale Positioning: Upper tier of medium-sized facilities to lower tier of large-scale facilities
- Significance of Simple Aggregation: Aggregate all records as an initial analysis phase to grasp total volume across active item counts, destination counts, total shipping case counts, total volume, and total weight.
3) "Fluctuations" of Shipping Volumes and Economical Facility Scale Design
Shipping volumes fluctuate daily due to seasons, months, days of the week, weather, sales, new store openings, etc. This is called "Shipping Fluctuations."
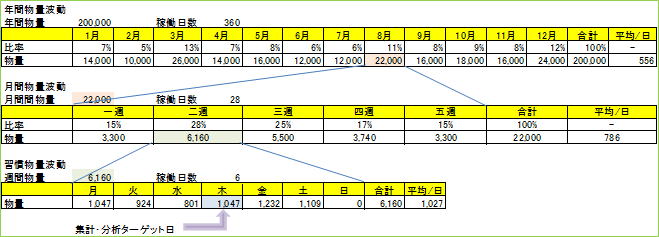
【Key Points for Economical Scale Design】
- Failure of Peak Day Design: Designing storage racks or material handling equipment aligned with annual or monthly peak days generates vast wasted space and excessive equipment during off-peak periods, becoming uneconomical.
- Target Day Selection: Tera Calculation selects a leveled specific day of the week (e.g., Thursday) rather than weekly maximum peak days as the target day for system design.
- Company-wide Agreement on Peak Measures: Excess volume on peak days is handled via "extended working hours," "temporary staffing," "external warehouse outsourcing," and "advanced shipment operations." As these operations impact sales and purchasing departments, forming company-wide agreements in advance is key to success.
4) Data Processing Logic (Tera Calculation 0)
After importing raw shipping data, automated processing executes through the following steps, generating the core "T200" Consolidated Data Table.
- Automatic Unit Conversion from Piece Quantity:
- Converted Case Value = Piece Quantity ÷ Case Pack Quantity
- Converted Pallet Value = Converted Case Value ÷ Pallet Case Stacking Quantity
- Converted Volume = Converted Case Value × Case Volume / Converted Weight = Converted Case Value × Case Weight
- Automated Separation of Case Shipping and Piece Shipping:
- Less than 1 Case (Case Value < 1) ──> Piece Shipping (Picking from operational racks)
- 1 Case or More with No Fraction (Case Value ≥ 1 and Fraction = 0) ──> Case Shipping (Whole case retrieval from inventory area)
- 1 Case or More with Fraction (e.g., ordering 9 items of a 5-pack product) ──> Automatically split into 1 case as Case Shipping and 4 pieces as Piece Shipping
- 5-Stage Ranking Classification (EIQ Analysis Extension):
Expanding conventional ABC analysis (3 categories), items and destinations are ranked into 5 categories: A1 (50%), A2 (20%), B (15%), C (10%), and D (5%).- Tera Calculation 1 (Shipping Capacity Design): Applies "Converted Case Value" for case shipping and "Issue Frequency (Line Count)" for piece shipping as ranking keys.
- Tera Calculation 2 (Storage Capacity Design): Applies "Converted Pallet Value" as ranking keys for both cases and pieces to calculate storage space.
- Consolidated Table "T200" Generation: Creating "T200" integrating converted values and various ranking details realizes high-speed aggregation processing.
5) Practical Operational Definitions and Precautions
- Record Count vs. Issue Frequency: When "1 case + 3 pieces" are shipped in 1 record, record count is 1, but since 2 processes occur (case retrieval and piece picking), issue frequency is counted as "2 times" to correctly calculate operational workload.
- Term Definitions (Put-away, Retrieval, Sorting, Picking):
- Put-away / Retrieval: Storage into and retrieval from storage space (racks, etc.).
- Sorting (Seeding): Distributing batch-retrieved products to individual destinations.
- Picking (Picking): Picking items from operational racks (flow racks, etc.) as instructed.
- Considering Peak Slot Advances: To schedule upstream processes (picking, replenishment) by calculating backward from shipping completion times, design accounts for time lags between work start and end times.